An outage is not the moment to decide who owns DNS, where backups live, or whether a failing checkout justifies rollback. A lightweight incident system gives even a small website team a common language, a response sequence, and evidence for improvement.
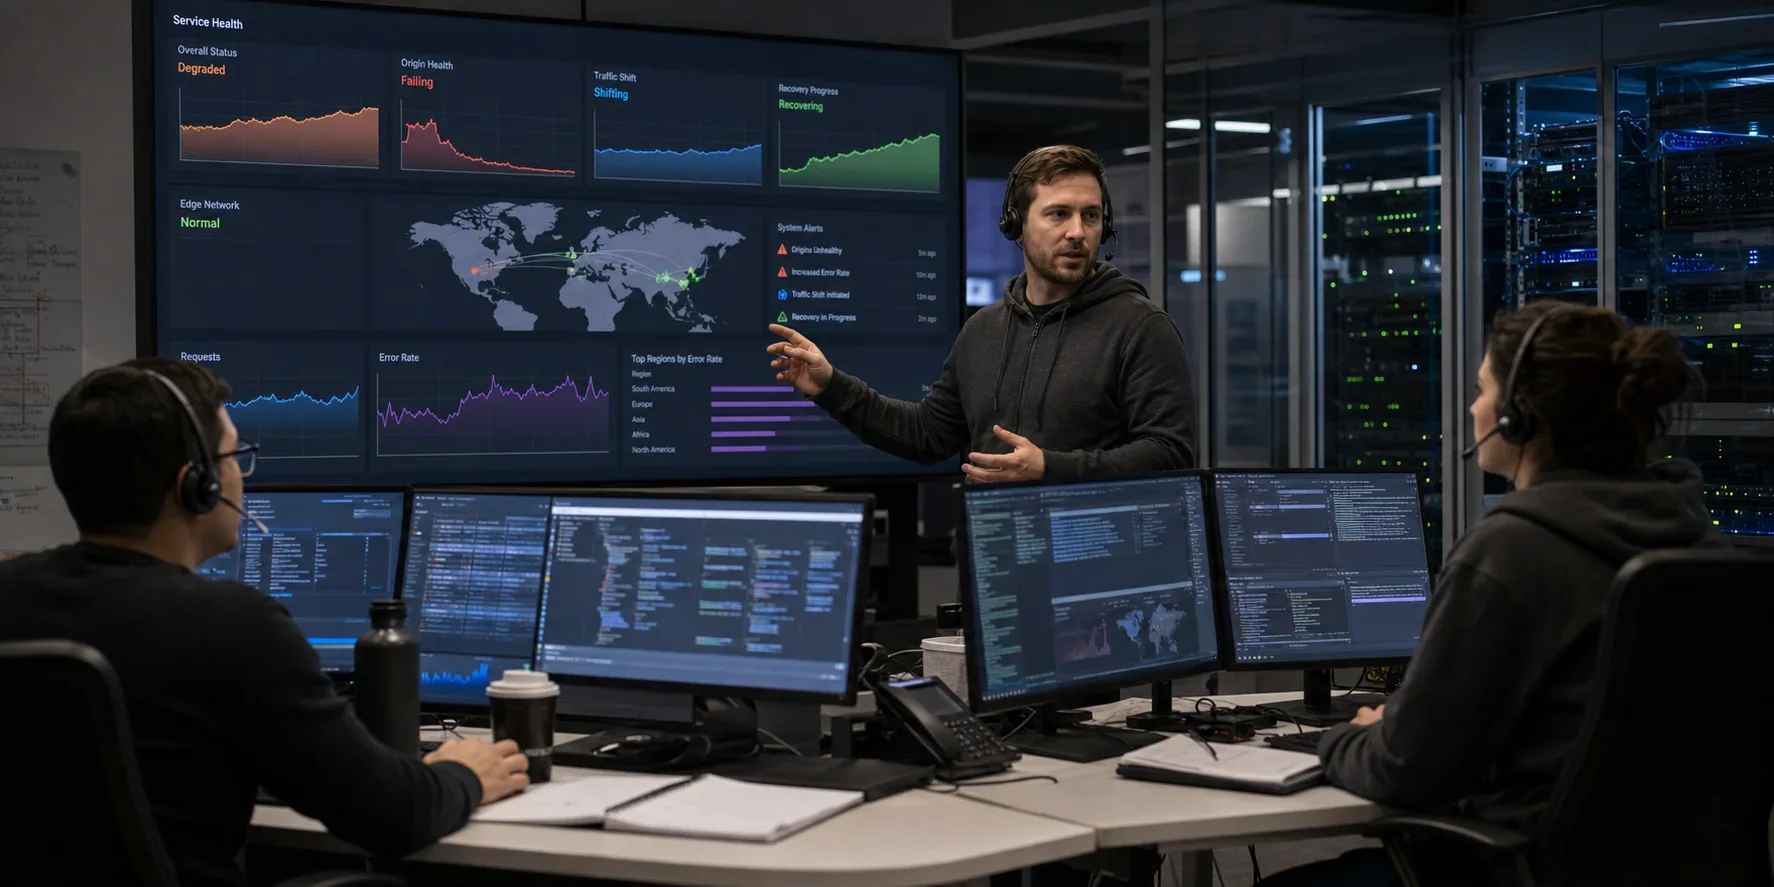
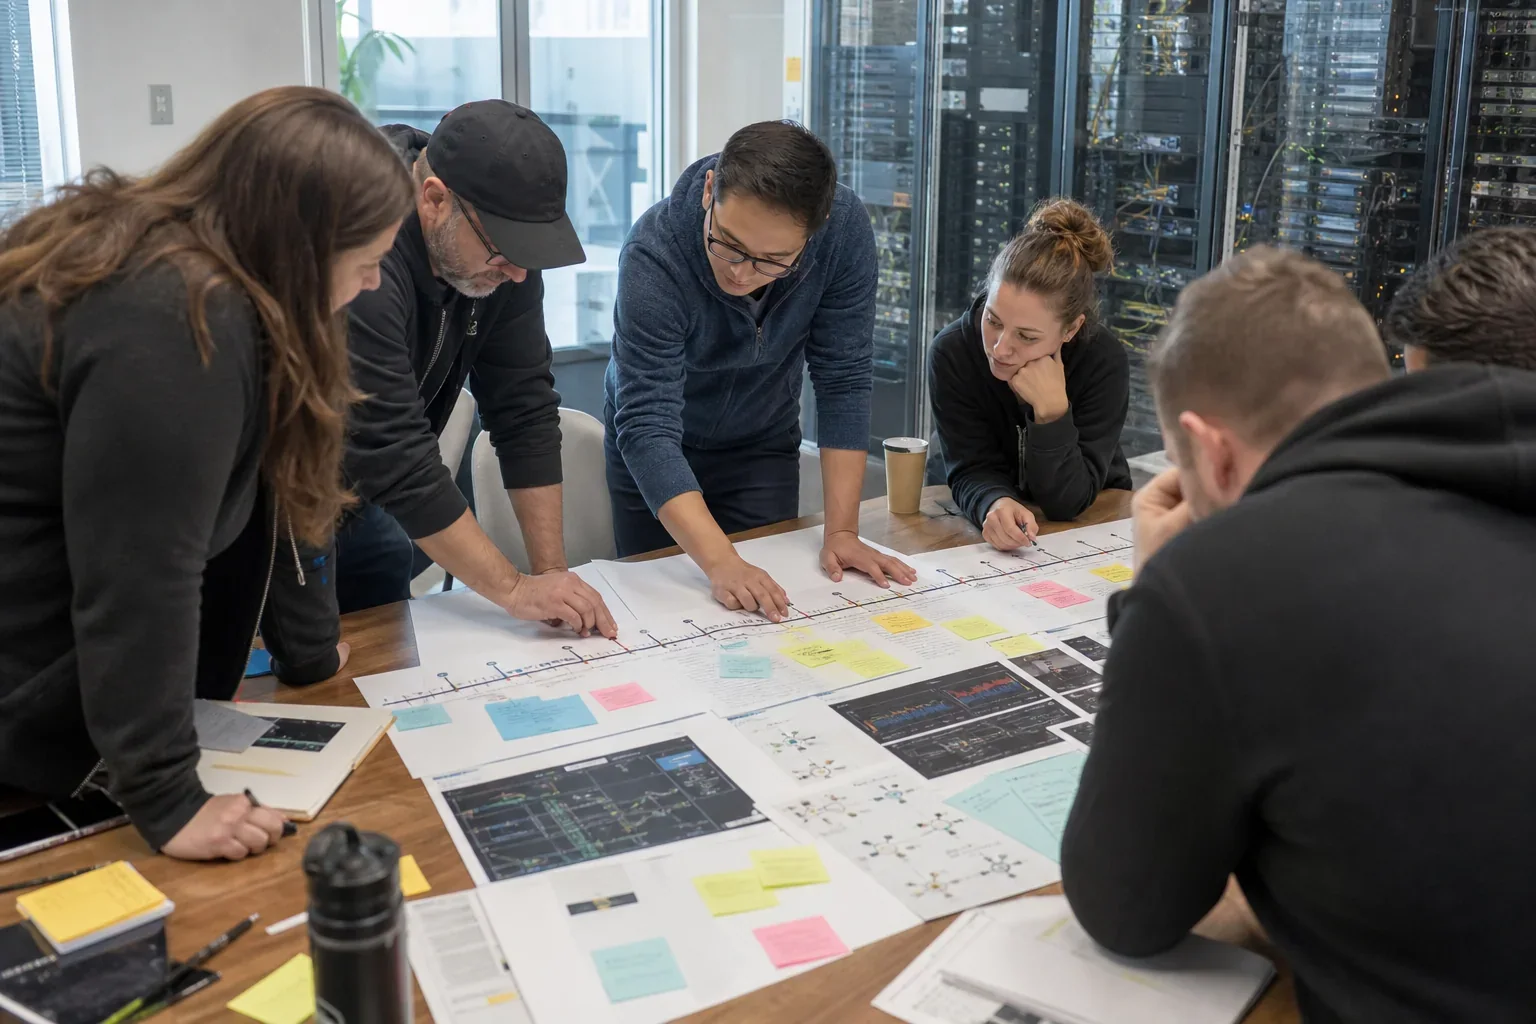
Image disclosure: These AI-generated images illustrate incident-management situations. Dashboard details are fictional and do not represent a real provider or ChoiceRidge measurement.
Short answer
Monitor from outside the hosting account, define severity and escalation, assign one incident lead, preserve evidence, stabilize the highest-impact user journeys, communicate verified facts, and recover through a rehearsed runbook. Afterward, write a blameless timeline with concrete corrective actions. Monitoring tells you something changed; observability helps explain why.
Prepare before the alarm
Maintain a service inventory with owners for domain, DNS, CDN, origin, database, storage, email, payments, code deployment, analytics, backups, and vendor support. Record emergency access, renewal dates, dependencies, support entitlements, and recovery instructions in a location available when the primary platform is down.
Define severity using business impact rather than technical drama:
| Severity | Example impact | Response expectation |
|---|---|---|
| Critical | Site unavailable, checkout or authentication broadly failing, active data loss or compromise | Immediate coordinated response and frequent updates |
| High | Major journey degraded or a significant audience affected | Rapid owner assignment and scheduled updates |
| Moderate | Limited feature, region, or workaround available | Track, investigate, and communicate to affected users |
| Low | Cosmetic or low-impact defect | Normal work queue |
Assign roles that can be combined in a small team: incident lead makes priorities, technical lead coordinates diagnosis and change, communications lead issues updates, and scribe records timeline and decisions. One person should not silently perform unrelated fixes while others investigate.
Detect what users actually experience
Use external uptime and synthetic journey monitoring from relevant regions. A successful home-page request does not prove that DNS, login, search, forms, checkout, webhooks, or transactional email work. Monitor certificate expiry, domain renewal, backup freshness, error rate, latency percentiles, resource saturation, database health, queues, and critical third-party dependencies.
AWS reliability guidance emphasizes monitoring the components that serve a workload and sending notifications when thresholds are crossed. Alert on actionable symptoms, group related events, and tune noise. An exhausted team that ignores frequent false positives does not have an effective monitoring system.
The first 15 minutes
- Acknowledge the alert and open an incident record.
- Confirm impact with an external check; do not rely only on the failing dashboard.
- Assign severity and roles.
- Freeze risky deployments and record recent changes.
- Check provider status, DNS, TLS, edge, origin, application, database, and dependencies.
- Choose the safest stabilizing action: rollback, traffic shift, cache bypass, feature disablement, capacity increase, or restore.
- Publish an initial status using verified scope and the next update time.
Do not announce a root cause before evidence supports it. “We are investigating elevated checkout errors” is more trustworthy than a confident but incorrect infrastructure diagnosis.
Stabilize, then investigate deeply
Protect data and user safety first. If a release correlates with the incident and rollback is tested, reversing it may be faster than debugging in production. If compromise is plausible, preserve logs and snapshots, restrict access, rotate exposed credentials, and avoid restoring vulnerable code without containment.
Use a timeline that combines deployments, configuration changes, provider events, traffic, errors, saturation, and user reports. Correlation is a lead, not proof. Capture query IDs, request IDs, timestamps, affected regions, status codes, and configuration versions so the investigation can be reproduced.
The NIST incident-response guidance integrates response into broader cybersecurity risk management. For a small site, the practical lesson is to connect preparation, detection, response, recovery, and lessons learned instead of treating each incident as an isolated support ticket.
Communicate without creating more risk
State what users experience, what the team is doing, available workarounds, and when the next update will arrive. Keep internal technical speculation out of customer updates. If personal data or contractual obligations may be involved, involve the appropriate legal and security owners; do not improvise disclosure timelines.
Maintain a communication channel that remains available if the website and primary email domain fail. After recovery, clearly state service restoration while continuing to monitor. Recovery is not proof that the root cause is understood.
Post-incident review
Hold the review after immediate pressure subsides but while evidence is fresh. Focus on system and process conditions, not personal blame.
Include:
- user and business impact, start, detection, mitigation, and end times;
- a sourced timeline of alerts, changes, decisions, and communications;
- technical cause and contributing conditions, with uncertainty labeled;
- why controls did not prevent or detect the issue sooner;
- what worked, what created delay, and where the runbook was wrong;
- actions with owner, due date, priority, and verification method.
Good actions change the system: add a synthetic checkout, automate certificate monitoring, test rollback quarterly, remove a single point of failure, or clarify escalation. “Be more careful” is not a control.
Incident-readiness checklist
- Service and dependency inventory has named owners
- External monitoring covers critical user journeys
- Severity, roles, and escalation contacts are documented
- Emergency credentials use MFA and are recoverable
- Backups have passed a recent isolated restore drill
- Deployment rollback and DNS/CDN change procedures are tested
- Status communication works outside the primary site
- Logs share reliable timestamps and useful identifiers
- Post-incident actions are tracked to verification
Use the ChoiceRidge Infrastructure & Hosting hub to connect operational readiness with provider research. The small-business hosting guide can help with selection, but no provider removes the need for business-owned escalation, recovery targets, and communication.
Method and limitations
This guide adapts official NIST and AWS reliability concepts for ordinary website operations. It is not a substitute for a formal security incident-response, legal, privacy, or regulated-industry program.