A fast demo page does not prove that a host can serve your real site on a busy day. Useful testing separates browser experience, origin response, application work, database pressure, cache effects, and reliability under sustained traffic. This framework produces evidence that can guide capacity and hosting decisions without manufacturing a universal “fastest host.”
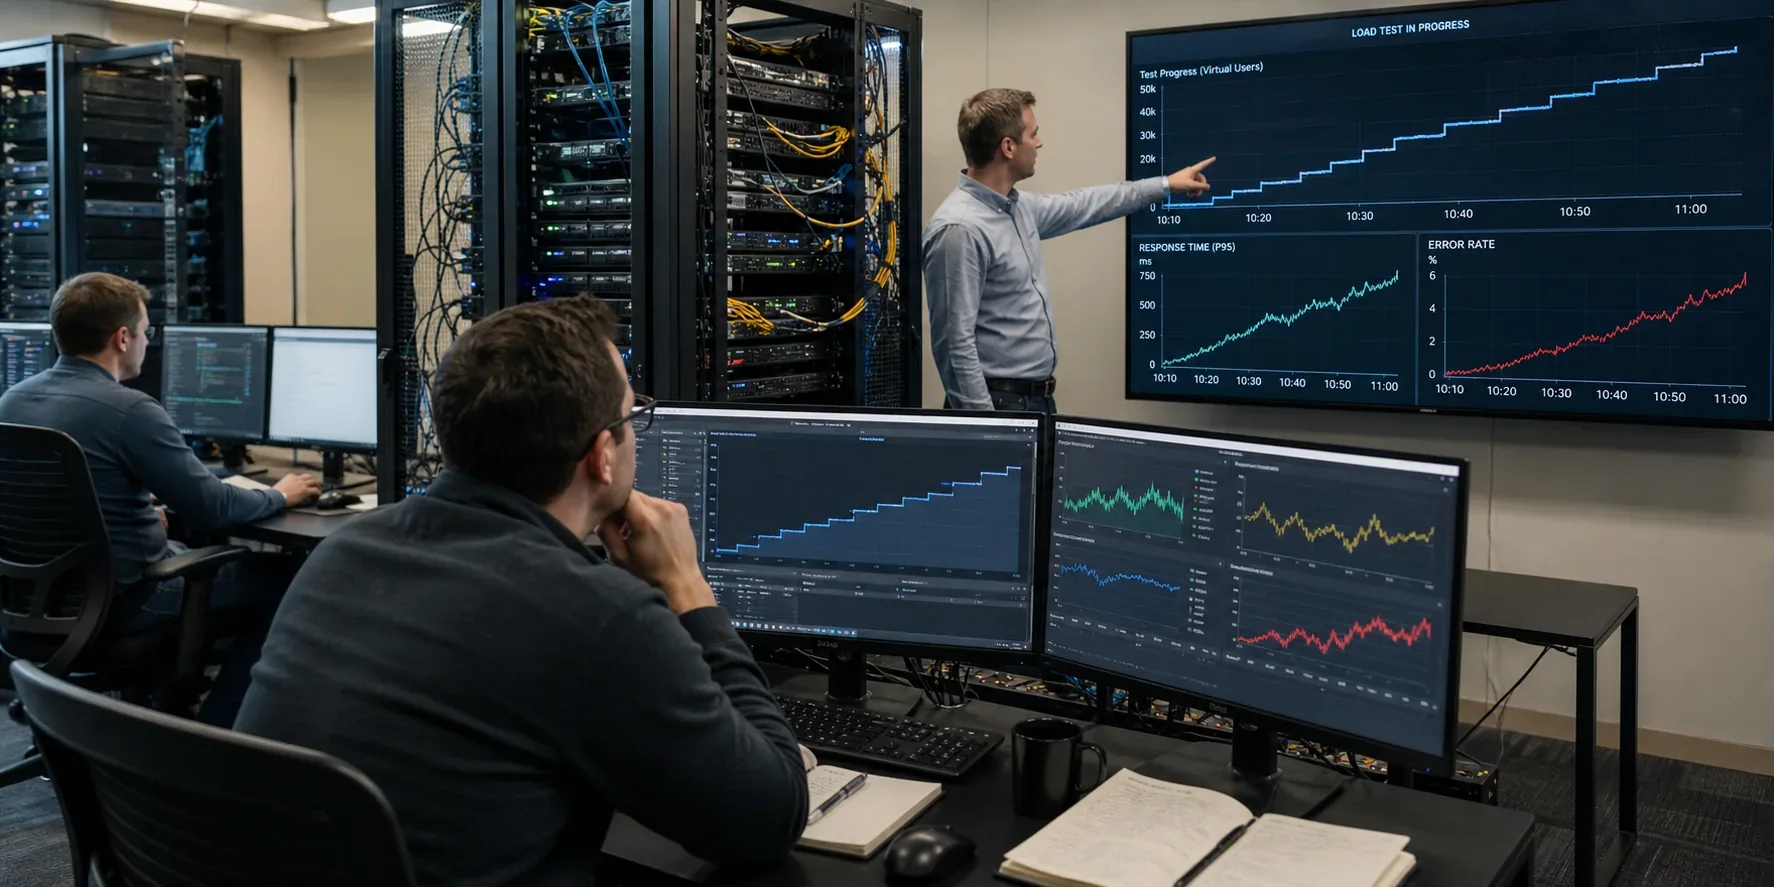
Image disclosure: The images are AI-generated editorial illustrations. They are not photographs of a ChoiceRidge benchmark or a named provider's infrastructure.
Short answer
Test representative user journeys on a production-like environment. Capture real-user Web Vitals, run repeatable synthetic checks from relevant regions, and use controlled load tests for capacity. Establish baselines and thresholds before each run, distinguish cached from uncached traffic, and stop tests that threaten a live service. Performance is a distribution over time, not one score.
Define the questions first
“Is this hosting fast?” is too broad. Replace it with questions such as:
- Can the origin keep the 95th-percentile response time below our target at expected peak concurrency?
- Does checkout remain reliable when background imports run?
- How much does a CDN improve anonymous pages, and what remains origin-bound?
- At what load do error rate, queue depth, CPU, memory, or database latency become unacceptable?
- Do actual visitors receive a good loading and interaction experience?
Document the site version, server plan, region, cache state, dataset size, plugins, test time, and network profile. Without this context, a benchmark is difficult to reproduce and easy to misuse.
Measure three layers
| Layer | Useful evidence | What it helps diagnose |
|---|---|---|
| User experience | LCP, INP, CLS and journey completion | What real or simulated visitors experience |
| Delivery path | DNS, connection, TLS, cache status, TTFB | Network, CDN and origin delay |
| Application capacity | request latency, throughput, errors, saturation | Server, runtime, database and dependency limits |
Google's current Core Web Vitals are LCP, INP, and CLS. Use field data when available because it reflects real devices and networks. Lab tests are valuable for diagnosis and regression checks, but they do not replace field distributions.
Build representative scenarios
A test plan should mirror business traffic rather than hammering one URL. Include the home page, a content page, search, login, account action, form submission, and checkout where relevant. Use safe test accounts and sandbox payments. Model read-heavy anonymous traffic separately from authenticated or transactional work because caching changes the infrastructure path.
Create a baseline under low load, then run:
- Smoke test: confirms the script and environment work.
- Average-load test: validates normal traffic for a sustained period.
- Stress test: increases load to identify the practical limit and failure behavior.
- Spike test: models abrupt campaigns or publicity.
- Soak test: reveals memory leaks, queue growth, or scheduled-job interference over time.
Grafana k6's official guidance recommends tests that reflect realistic load patterns and thresholds that turn performance expectations into pass/fail criteria. Coordinate with the hosting provider before load testing; some services prohibit unapproved tests or may interpret them as an attack.
Use thresholds, not impressions
Set thresholds before seeing results. Examples include a maximum failure rate, a 95th-percentile request duration, and a minimum successful-journey rate. Do not rely only on averages: a tolerable mean can hide a slow tail that affects many users.
Watch application and infrastructure signals during the run—CPU, memory, disk I/O, database connections and slow queries, PHP workers, queue depth, cache hit ratio, upstream API latency, and rate-limit responses. A plateau in throughput combined with growing latency usually signals saturation, but the responsible component requires telemetry.
Prevent benchmark mistakes
- Warm and cold cache runs answer different questions; label both.
- A CDN-cached page is not evidence of database capacity.
- Testing an empty installation does not represent a mature site.
- One geographic probe does not represent global visitors.
- Synthetic mobile emulation does not capture every real-device constraint.
- A short spike cannot prove long-term stability.
- Comparing plans with different application configurations is not a clean host comparison.
- Running uncontrolled traffic against production can harm users and corrupt analytics.
Use a staging clone with realistic, anonymized data for capacity experiments. If a production validation is necessary, schedule it, set conservative abort conditions, inform stakeholders, protect transactional data, and monitor actively.
Turn results into a capacity decision
Report the workload and the breaking point together. For example: at a specified request mix and duration, the system met all thresholds until a defined concurrency, after which database wait and error rate increased. That is actionable; “the host scored 92” is not.
Optimize the measured bottleneck first. Options may include page or object caching, query correction, image delivery, fewer blocking third-party scripts, more workers, database capacity, or a different architecture. Retest the same scenarios after each material change. Keep the test scripts in version control and rerun them before large campaigns or platform changes.
If evidence shows the operating model—not only the plan size—is wrong, use the ChoiceRidge Infrastructure & Hosting hub and small-business hosting guide for the next selection step. Provider comparisons should not be treated as a substitute for testing your workload.
Minimum reporting template
- objective and acceptance thresholds;
- environment, region, application version and data size;
- scenarios, traffic mix, duration and ramp pattern;
- cache/CDN state and test-tool version;
- percentiles, throughput, errors, saturation and Web Vitals;
- incidents, invalid samples and limitations;
- conclusion tied to the tested workload, not all websites.
Method and limitations
This framework uses official Web Vitals and k6 guidance. It does not present original ChoiceRidge benchmark data. Results depend on the application, provider policy, plan, location, dataset, test design, and time; they should be reproduced before a purchasing or scaling decision.